数据编码

1. 什么是数据编码

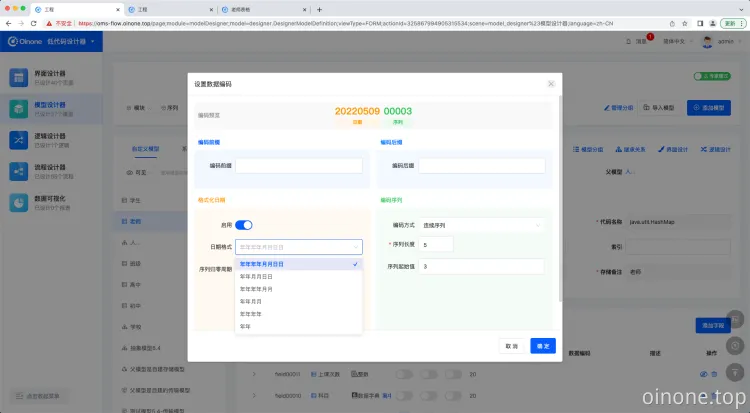
当模型中的字段数据需要有一定的编码规定,可以在模型中设计模型或字段的数据编码。

image.png

  • 编码预览:实时展示规则设置后的编码。

2. 编码前/后缀

  • 编码前缀:必须以字母开头,且仅支持数字或字母,最多8个字符。
  • 编码后缀:必须以字母开头,且仅支持数字或字母,最多8个字符。

3. 格式化日期

  • 开关默认关闭,即数据编码中不包含日期。开关打开后,默认的日期格式为“年年年年月月日日”,也可以切换成“年年月月日日、年年月月、年年年年、年年”。
  • 序列归零周期:与格式化日期选择有关,若选择为“年年年年月月日日”,则可选“年、月、日”,选择为“年年年年”,则只可选“年”数据编码序列会按照设置的这个周期归零。

4. 编码序列

  • 编码方式:可选择连续序列或非连续序列,选择会影响后续包含哪些设置。
  • 序列长度:序列包含多少位数字,可以设置1 - 18之间的整数。
  • 序列起始值:数据编码序列的起始值,默认值为3。

当编码方式设置为非连续序列时,展示其余两个配置项。

  • 步长类型:默认值为“自定义步长”,也可以设置成“1 - 10之间随机步长”。
  • 步长:当选择“自定义步长”时,设置的步长即为真实步长。当选择“1 - 10之间随机步长”时,实际步长为1 - 设置值之间的随机整数。

Oinone社区 作者:史, 昂原创文章,如若转载,请注明出处:https://doc.oinone.top/oio4/9401.html

访问Oinone官网:https://www.oinone.top获取数式Oinone低代码应用平台体验

Like (0)
史, 昂's avatar史, 昂数式管理员
Previous 2024年6月20日 am9:49
Next 2024年6月20日

相关推荐

  • 4.5.2 研发辅助之SQL优化

    Oinone体系中是不需要针对模型写SQL的,默认提供了通用的数据管理器。在带来便利的情况下,也导致传统的sql审查就没办法开展。但是我们可以以技术的手段收集慢SQL和限制问题SQL执行。 慢SQL搜集目的:去发现非原则性问题的慢SQL,并进行整改 限制问题SQL执行:对应一些不规范的SQL系统上直接做限制,如果有特殊情况手动放开 一、发现慢SQL 这个功能并没有直接加入到oinone的版本中,需要业务自行写插件,插件代码如下。大家可以根据实际情况进行改造比如: 堆栈入口,例子中只是放了pamirs,可以根据实际情况改成业务包路径 对慢SQL的定义是5s还是3s,根据实际情况变 package pro.shushi.pamirs.demo.core.plugin; import org.apache.ibatis.executor.Executor; import org.apache.ibatis.mapping.MappedStatement; import org.apache.ibatis.plugin.*; import org.apache.ibatis.session.ResultHandler; import org.apache.ibatis.session.RowBounds; import org.springframework.stereotype.Component; import pro.shushi.pamirs.meta.annotation.fun.extern.Slf4j; @Intercepts({ @Signature(type = Executor.class,method = "query",args = {MappedStatement.class,Object.class, RowBounds.class, ResultHandler.class}) }) @Component @Slf4j public class SlowSQLAnalysisInterceptor implements Interceptor { @Override public Object intercept(Invocation invocation) throws Throwable { long start = System.currentTimeMillis(); Object result = invocation.proceed(); long end = System.currentTimeMillis(); if (end – start > 10000) {//大于10秒 try { StackTraceElement[] stackTraceElements = Thread.currentThread().getStackTrace(); StringBuffer slowLog = new StringBuffer(); slowLog.append(System.lineSeparator()); for (StackTraceElement element : stackTraceElements) { if (element.getClassName().indexOf("pamirs") > 0) { slowLog.append(element.getClassName()).append(":").append(element.getMethodName()).append(":").append(element.getLineNumber()).append(System.lineSeparator()); } } Object parameter = null; if (invocation.getArgs().length > 1) { parameter = invocation.getArgs()[1]; } MappedStatement mappedStatement = (MappedStatement) invocation.getArgs()[0]; BoundSql boundSql = mappedStatement.getBoundSql(parameter); Configuration configuration = mappedStatement.getConfiguration(); String originalSql = showSql(configuration, boundSql); originalSql = originalSql.replaceAll("\'", "").replace("\"", ""); log.warn("检测到的慢SQL为:" + originalSql); log.warn("业务慢SQL入口为:" + slowLog.toString()); } catch (Throwable e1) { //忽略 } } return result; } public String showSql(Configuration configuration, BoundSql boundSql) { Object parameterObject = boundSql.getParameterObject(); List<ParameterMapping> parameterMappings = boundSql.getParameterMappings(); String sql = boundSql.getSql().replaceAll("[\\s]+", " "); if (parameterMappings.size() > 0 && parameterObject != null) { TypeHandlerRegistry typeHandlerRegistry…

    Oinone 7天入门到精通 2024年5月23日
    2.1K00
  • 3.5.6.3 布局的配置

    布局是将页面拆分成一个一个的小单元,按照上下中左右进行排列。 前沿 在前端领域中,布局可以分为三大块「Float、Flex、Grid 」,Float可以说的上是上古时期的布局了,如今市面还是很少见的,除了一些古老的网站。 目前,平台主要支持通过配置XML上面的cols和span来进行布局。平台也同样支持自由布局,合理的使用row、col、containers和container四个布局容器相关组件,将可以实现各种类型的布局样式,换句话说,平台实现的自由布局功能是Flex和Grid的结合体。 这里主要是讲解Flex和Grid布局,以及目前新的模板布局实现的思路。 Flex布局 Flex布局采用的是一维布局,那么什么是一维布局呢,所谓的一维布局就是只有一个方向、没有体积、面积,比如一条直线。它适合做局部布局,就像我们原来的顶部菜单、面包屑导航,以及现在的主视图字段配置。 图3-5-6-19 Flex布局示意 图3-5-6-20 Flex布局示意 图3-5-6-21 Flex布局示意 从上图可以看看出,Flex布局只能在X、Y轴进行转换,它无法对上下左右四个方向同时处理,因为它没“面积”的概念。所以它最适合做局部布局。 优点 图3-5-6-22 Flex兼容性 Flex的兼容性,可以看得出来,目前主流的浏览器都支持该属性。所以Flex兼容性强,如果你想对局部做布局处理,Flex是最好选择。 缺陷 刚刚也提到了,用户想要的布局是千奇百怪的,如果他想要的布局在现有的功能中无法实现怎么办?让用户放弃?还是说服他使用现在的布局。 Grid布局 Grid布局系统采用的是二维布局,二维布局有四个方向:上、下、左、右,它只有面积没有体积,比如一张纸、网格。 Grid布局 <div id="grid-container-one"> <div class="one-1">Grid Item 1</div> <div>Grid Item 2</div> <div>Grid Item 3</div> <div>Grid Item 4</div> <div>Grid Item 5</div> <div class="one-6">Grid Item 6</div> </div> <div id="grid-container-two"> <div class="tow-1">Grid Item 1</div> <div class="tow-2">Grid Item 2</div> <div>Grid Item 3</div> <div>Grid Item 4</div> <div>Grid Item 5</div> <div>Grid Item 6</div> </div> <div id="grid-container-three"> <div>Grid Item 1</div> <div>Grid Item 2</div> <div class="grid">Grid Item 3</div> <div class="grid-column">Grid Item 4</div> <div>Grid Item 5</div> <div>Grid Item 6</div> <div>Grid Item 7</div> <div class="grid-column">Grid Item 8</div> </div> HTML CSSResult Skip Results Iframe EDIT ON * { box-sizing: border-box; padding: 0; margin: 0; line-height: 1.5; font-weight: bold; text-align: center; } #grid-container-one{ background-color: black; display: grid; grid-template-columns: repeat(3, 1fr); grid-template-rows: repeat(2, 50px); gap: 10px; border: solid black 2px; margin-bottom: 20px; color: salmon; } #grid-container-one div { border: solid white 2px; padding: 10px; } #grid-container-one .one-1 { grid-area: span 1/span 3; text-aligin: center } #grid-container-one .one-6 { grid-column: 3 /4; } #grid-container-two{ background-color: CADETBLUE; display: grid; grid-template-columns: 15% repeat(2, 1fr);…

    2024年5月23日
    1.7K00
  • 书籍封面

    2024年5月23日
    3.7K00
  • 3.4.3.3 SPI机制-扩展点

    扩展点结合拦截器的设计,oinone可以点、线、面一体化管理Function 扩展点用于扩展函数逻辑。扩展点类似于SPI机制(Service Provider Interface),是一种服务发现机制。这一机制为函数逻辑的扩展提供了可能。 一、构建第一个扩展点 自定义扩展点(举例) 在我们日常开发中,随着对业务理解的深入,往往还在一些逻辑中会预留扩展点,以便日后应对不同需求时可以灵活替换某一小块逻辑。 在3.3.4【模型的继承】一文中的PetCatItemQueryService,是独立新增函数只作公共逻辑单元。现在我们给它的实现类增加一个扩展点。在PetCatItemQueryServiceImpl的queryPage方法中原本会先查询PetCatType列表,我们这里假设这个逻辑随着业务发展未来会发生变化,我们可以预先预留【查询萌猫类型扩展点】 Step1 新增扩展点定义PetCatItemQueryCatTypeExtpoint 扩展点命名空间:在接口上用@Ext声明扩展点命名空间。会优先在本类查找@Ext,若为空则往接口向上做遍历查找,返回第一个查找到的@Ext.value注解值,使用该值再获取函数的命名空间;如果未找到,则返回扩展点全限定类名。所以我们这里扩展点命名空间为:pro.shushi.pamirs.demo.api.extpoint.PetCatItemQueryCatTypeExtpoint 扩展点技术名称:先取@ExtPoint.name,若为空则取扩展点接口方法名。所以我们这里技术名为queryCatType package pro.shushi.pamirs.demo.api.extpoint; import pro.shushi.pamirs.demo.api.model.PetCatType; import pro.shushi.pamirs.meta.annotation.Ext; import pro.shushi.pamirs.meta.annotation.ExtPoint; import java.util.List; @Ext public interface PetCatItemQueryCatTypeExtpoint { @ExtPoint(displayName = "查询萌猫类型扩展点") List<PetCatType> queryCatType(); } 图3-4-3-11 新增扩展点定义PetCatItemQueryCatTypeExtpoint Step2 修改PetCatItemQueryServiceImpl(用Ext.run模式调用) 修改queryPage,增加扩展点的使用代码。扩展点的使用有两种方式 方法一,使用命名空间和扩展点名称调用Ext.run(namespace, fun, 参数); 方法二,使用函数式接口调用Ext.run(函数式接口, 参数); 我们这里用了第二种方式 用PetCatItemQueryCatTypeExtpoint的全限定类名作为扩展点的命名空间(namespace) 用queryCatType的方法名作为扩展点的技术名称(name) 根据namespace+name去找到匹配扩展点实现,并根据规则是否匹配,以及优先级唯一确定一个扩展点实现去执行逻辑 package pro.shushi.pamirs.demo.core.service; ……省略依赖包 @Model.model(PetCatItem.MODEL_MODEL) @Component public class PetCatItemAction extends DataStatusBehavior<PetCatItem> { @Override protected PetCatItem fetchData(PetCatItem data) { return data.queryById(); } @Action(displayName = "启用") public PetCatItem dataStatusEnable(PetCatItem data){ data = super.dataStatusEnable(data); data.updateById(); return data; } @Function.Advanced(displayName = "查询模型数据的默认过滤条件", type = FunctionTypeEnum.QUERY, managed = true) @Function(openLevel = {LOCAL}) public String queryFilters() { StringBuilder sqlWhereCondition = new StringBuilder(); // List<PetCatType> typeList = new PetCatType().queryList(); List<PetCatType> typeList = Ext.run(PetCatItemQueryCatTypeExtpoint::queryCatType, new Object[]{}); if(!CollectionUtils.isEmpty(typeList)){ // sqlWhereCondition.append("type_id"); sqlWhereCondition.append(PStringUtils.fieldName2Column(LambdaUtil.fetchFieldName(PetCatItem::getTypeId))); sqlWhereCondition.append(StringUtils.SPACE).append(SqlConstants.IN).append(CharacterConstants.LEFT_BRACKET); for(PetCatType petCatType: typeList){ sqlWhereCondition.append(petCatType.getId()).append(CharacterConstants.SEPARATOR_COMMA); } sqlWhereCondition.deleteCharAt(sqlWhereCondition.lastIndexOf(CharacterConstants.SEPARATOR_COMMA)); sqlWhereCondition.append(StringUtils.SPACE).append(CharacterConstants.RIGHT_BRACKET); } return sqlWhereCondition.toString(); } ……省略其他函数 } 图3-4-3-12 修改PetCatItemQueryServiceImpl Step3 新增扩展点实现PetCatItemQueryCatTypeExtpointOne 扩展点命名空间要与扩展点定义一致,用@Ext(PetCatItemQueryCatTypeExtpoint.class) @ExtPoint.Implement声明这是在@Ext声明的命名空间下,且技术名为queryCatType的扩展点实现 package pro.shushi.pamirs.demo.core.extpoint; import pro.shushi.pamirs.demo.api.extpoint.PetCatItemQueryCatTypeExtpoint; import pro.shushi.pamirs.demo.api.model.PetCatType; import pro.shushi.pamirs.meta.annotation.Ext; import pro.shushi.pamirs.meta.annotation.ExtPoint; import pro.shushi.pamirs.meta.api.session.PamirsSession; import java.util.List; @Ext(PetCatItemQueryCatTypeExtpoint.class) public class PetCatItemQueryCatTypeExtpointOne implements PetCatItemQueryCatTypeExtpoint { @Override @ExtPoint.Implement(displayName = "查询萌猫类型扩展点的默认实现") public List<PetCatType> queryCatType() { PamirsSession.getMessageHub().info("走的是第一个扩展点"); List<PetCatType> typeList = new PetCatType().queryList(); return typeList; } } 图3-4-3-13 新增扩展点实现PetCatItemQueryCatTypeExtpointOne Step4…

    2024年5月23日
    2.0K00
  • 李强

    我们常说“在今天所有的不确定性当中,数字化是最大的确定性”,数字化一定会全面改造所有的行业更是确定的。在菜鸟九年的探索中,我们最大的感受是“未来,任何一个物流企业都会是一个技术公司,真正拉开差距的是:技术与实体产业的结合有多深”。菜鸟“简单极致,贴地疾飞”的技术文化也深刻体现了这一点——好的技术要能解决实际问题。数字化并不是简单地上线一个或几个系统,这是一个贴近业务持续迭代的过程,伴随着这个过程,我相信会诞生非常多的创新技术。 在本书中我看到了工程思维在推进技术创新的缩影,把难的问题转化为简单的问题,用成熟实用的技术分而解之。高性能的微服务框架、CDM、元数据、低代码、无代码等,都是当下非常热门的技术课题,Oinone把这一切都有机地结合起来,形成了一种具备先进理念的全新一代软件产品,每一个特性都贴合企业数字化遇到的实际问题。Oinone的产品设计,把“大道至简,软件自造”贯穿始终,用最简单的方式,帮助企业驾驭数字化,相信会给企业带来不一样的体验。 就跟本书提到的“「企业视角由内部管理转向业务在线、生态在线(协同)带来一系列新的诉求」这一大背景下,以及云、端等新技术的发展,对研发人员的需求越来越大,同时要求越来越高,低代码平台是提升研发效率,降低研发成本的核心手段”,低代码已经不是需不需要的问题,而是怎么选的问题。菜鸟网络自身也在推进自有低代码开发平台,我们有幸邀请本书作者陈鹏程来到菜鸟网络进行了分享交流,收获非常大。如您正在选型低代码开发平台,向您推荐这本书,低无一体的Oinone肯定会打动您。 菜鸟网络CTO李强(在宽)

    Oinone 7天入门到精通 2024年5月23日
    2.7K00

Leave a Reply

Please Login to Comment